Since the rise of large language models, OpenAI (ChatGPT) and Anthropic (Claude) have become core intelligence providers for technology companies worldwide. For teams in restricted regions or those building large-scale AI agent services, however, unstable API connections and frequent blocks remain a constant threat.
1. Three common problems with AI API calls
- “403 Forbidden / Access Denied”: Cloudflare or OpenAI’s edge gateway blocks the request before it reaches the model’s inference backend.
- Account restrictions and bans: An account holding hundreds of dollars in API Credits suddenly receives a suspension notice for violating the terms of use.
- Dropped streaming connections (SSE Dropping): While the model generates a long response, a standard proxy network may reset the connection, leaving the client with an incomplete stream of tokens.
2. IP reputation and AI service access checks
OpenAI and Claude must follow strict compliance policies and prevent attackers from using cloud VPS infrastructure for credential stuffing or abuse of free credits. They therefore rely on real-time IP reputation databases:
Why requests are blocked: hosting ASNs and abuse history
A hosting ASN or a history of abuse can affect an AI service’s risk assessment. The service may also evaluate regional availability, account permissions, and request behavior.
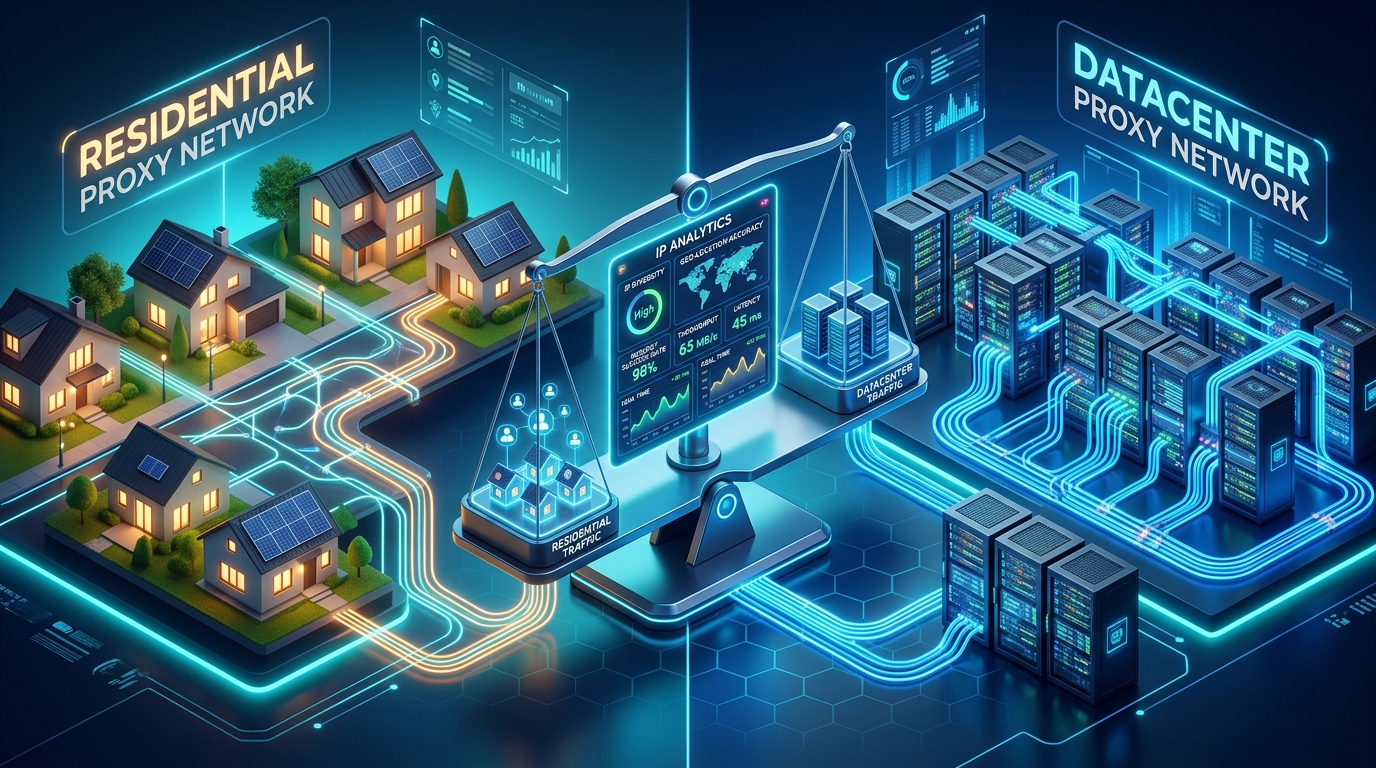
By contrast, requests made through dedicated static residential IPs provide a consistent network identity. Their classification does not override the AI service’s regional rules or account requirements.
3. The design of IP123 dedicated AI networks
For demanding production environments, IP123 offers dedicated proxy connections for AI:
- 100% dedicated, clean exit IPs: Each business receives its own exit IP, avoiding reputation damage caused by other users.
- Choose a region supported by your AI service: Check the available proxy locations and test time to first token with your own API workload. Latency depends on the route, target service, model, and request.
- Test streaming responses: Configure timeouts and reconnection handling in your application, then test a long SSE response through the assigned static endpoint.
4. SSE interruptions and reconnection strategies
In production, developers should configure appropriate retries and timeouts at the application layer:
- Separate connection and read timeouts: Set the connection timeout to 5 seconds and the read timeout to 90 seconds, giving the model time to complete complex reasoning.
- Send health-check heartbeats: Have a persistent local client send a lightweight probe to the proxy gateway every 60 seconds to keep the TCP connection pool active.
5. Minimal Node.js / Python integration
The following SDK example uses a placeholder endpoint. Replace it with the IP, port, username, and password from your dashboard, and check the current SDK’s proxy configuration.
Use dedicated static IPs to keep a consistent connection address for your AI workflows. Test connectivity and streaming behavior with your target service, and contact support if the proxy connection fails.