Real-time collection of large volumes of web data is essential for LLM training datasets, e-commerce price analysis, public-opinion monitoring, and industry-specific RAG knowledge bases. Today, however, more than 70% of high-value sites use enterprise WAFs such as Cloudflare, Akamai, DataDome, or Kasada. A fixed IP and simple User-Agent changes alone are not enough; the client’s protocol fingerprint and request behavior also matter.
1. The evolution of modern anti-bot systems
Anti-bot technology has evolved through four distinct stages as web scraping techniques have developed:
- First generation — static signals: Inspect HTTP headers such as
User-Agent,Referer,Host, and apply per-IP rate limiting. - Second generation — JavaScript challenges: Inject obfuscated JavaScript, calculate proof of work (PoW), and detect headless browser signals (
window.navigator.webdriver). - Third generation — network and protocol fingerprints: Compare the cipher suites in TLS Client Hello messages (JA3/JA4) and the SETTINGS and WINDOW_UPDATE frame patterns used when establishing HTTP/2 connections.
- Fourth generation — AI behavior profiling and multimodal verification: Combine gyroscope and mouse movement patterns, keystroke timing entropy, Turnstile challenges, and dynamic blocking based on network-wide IP reputation data.
2. TLS fingerprints: JA3/JA4 and HTTP/2 frames
Developers often ask, “Why does Cloudflare still block my Python Requests code immediately after I add a proxy?” The answer lies in the TLS Client Hello fingerprint.
During a TLS handshake, Python’s default urllib3 / OpenSSL stack sends lists of supported cipher suites, extensions, and elliptic-curve groups that differ substantially from those of a real Google Chrome browser:
A revealing signal: the JA3 fingerprint of Python Requests
Common Python libraries have highly consistent JA3 fingerprints, which almost every WAF recognizes and blocklists as obvious crawler traffic. Even with a pool of 100,000 clean static residential IPs, the WAF can return 403 Forbidden or trigger a five-second challenge before any HTTP request data is sent.
To address TLS fingerprinting, modern scrapers need networking libraries that support TLS spoofing, such as curl_cffi or tls-client, to reproduce handshake messages with characteristics that match Chrome or Firefox 100%.
3. Understanding Cloudflare challenges and Turnstile
Cloudflare Turnstile is gradually replacing traditional reCAPTCHA. It silently performs complex computations on the client and evaluates the connecting IP’s reputation:
- Faster verification for clean IPs: Turnstile evaluates multiple signals. A residential IP alone does not guarantee verification success; test with the target site and handle challenges according to its requirements.
- Extra challenges for datacenter IPs: For requests from known datacenter ranges, the WAF can require one or more interactive checkboxes even when the browser fingerprint looks realistic, substantially slowing automated collection.
4. Designing a high-throughput hybrid proxy pool
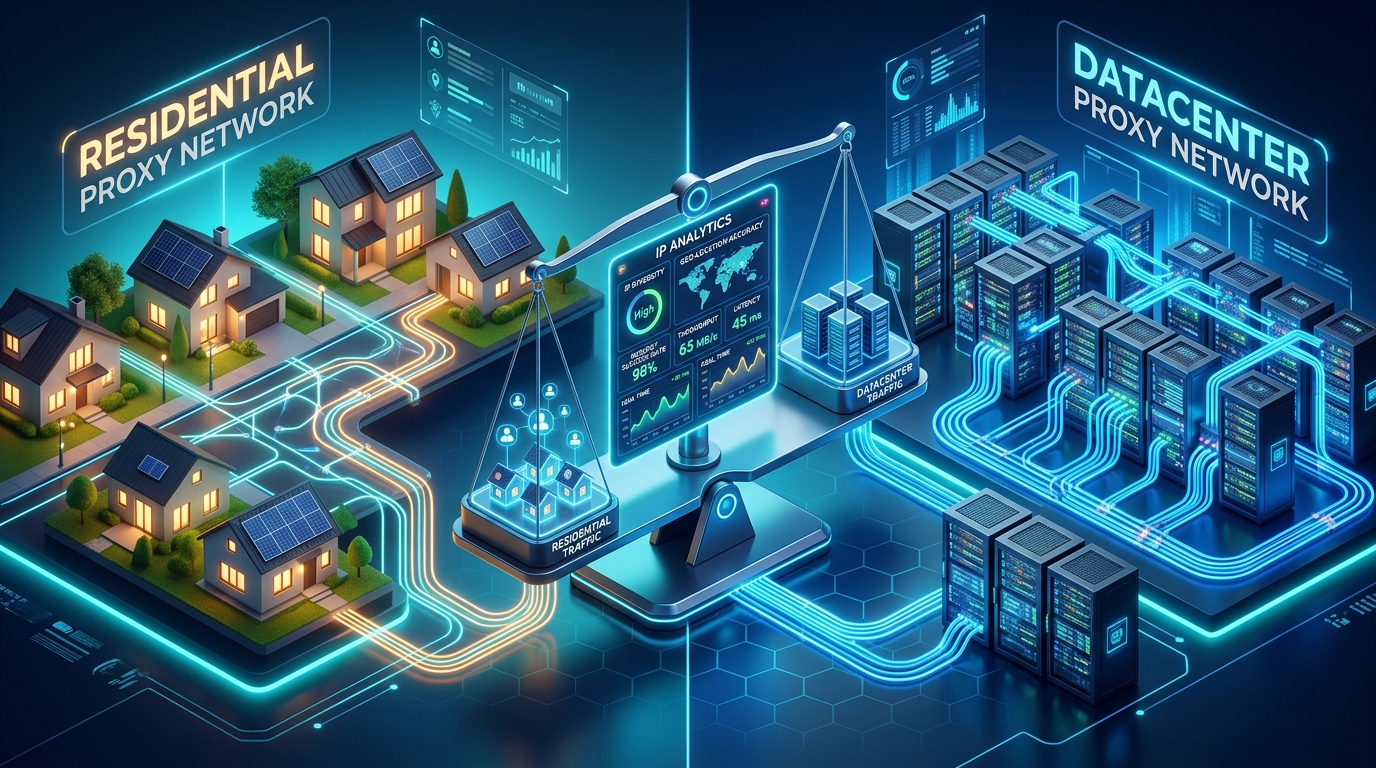
For large-scale enterprise data collection, a mature production architecture uses a two-layer proxy gateway that separates different classes of traffic, rather than routing every request through expensive residential IPs:
5. Python automation and session persistence
The following illustrative example uses curl_cffi with a placeholder proxy endpoint. Replace the endpoint and target URL with your actual settings; the example does not guarantee access to a protected page.
A modern scraping cluster combines a capable TLS emulation client with reputable native residential proxies. IP123 nodes support highly concurrent short-lived and persistent connections, with high availability for large-scale data collection.